Experiment ID:
EXP-001
Category:
Prompt Design
Status: Completed
About This Research
This document records observations from a structured prompt comparison conducted in one ChatGPT session. The test illustrates how different types of context may affect AI-generated responses under the documented conditions; it does not establish universal conclusions.
Research Question
How did adding examples and audience-specific context affect the specificity, practical value, and audience relevance of ChatGPT’s responses to three prompts about AI slop in one documented session?
Objective
This experiment documents how ChatGPT’s responses differed across three prompts about AI slop: a broad prompt, an example-based prompt, and an audience-specific prompt for SEO writers. The comparison focuses on observable differences in response specificity, practical value, and audience relevance within the recorded session. It is an exploratory observation, not a controlled benchmark or a test of all possible causes of generic AI responses.
Test Environment
| Item | Details |
| Model | ChatGPT |
| Test Date | 27 July 2026 |
| Number of Prompts | 3 |
| Topic | AI Slop |
| Evaluation Criteria | Specificity, Practical Value, Audience Relevance |
Prompts Used
Prompt 1
Explain AI Slop.
Prompt 2
Explain AI Slop with real examples.
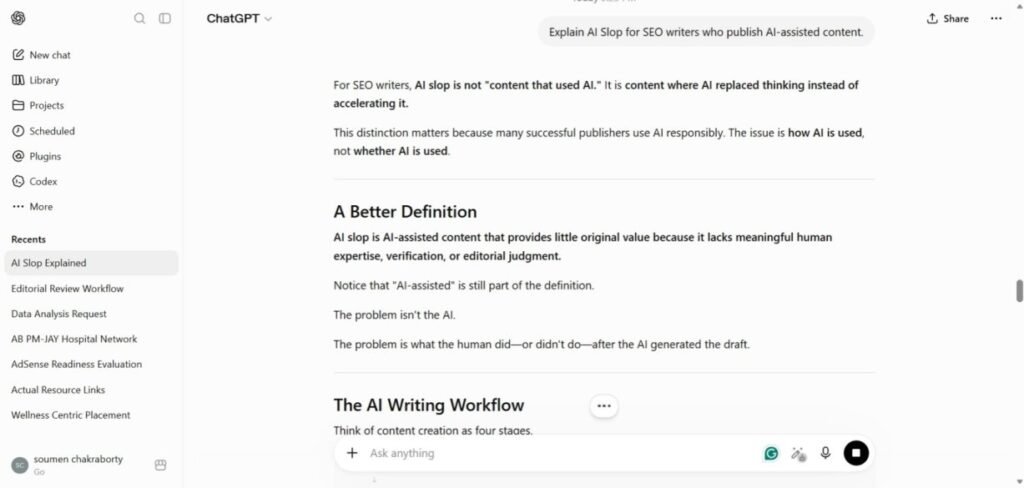
Prompt 3 Explain AI Slop for SEO writers who publish AI-assisted content.
Results
| Prompt | Observed Response Characteristics |
|---|---|
| Explain AI Slop. | Produced a broad definition of AI slop and outlined its general characteristics without audience-specific context. |
| Explain AI Slop with real examples. | Added practical examples that made the explanation more concrete and easier to understand while remaining broadly applicable. |
| Explain AI Slop for SEO writers who publish AI-assisted content. | Tailored the explanation to a specific audience and included workflow-oriented guidance relevant to SEO publishing. |
Key Finding & Analysis
The Impact of Context on AI Output Specificity
In this documented test session, the three prompts produced responses with different levels of specificity and audience focus. The generic prompt generated a broad overview, the example-based prompt produced more concrete explanations, and the audience-specific prompt provided guidance relevant to SEO writers. These observations illustrate differences between the tested prompts but do not establish that adding context will always improve AI responses.
Limitations
This experiment represents a single testing session using one AI model and three prompts. Results may vary depending on the AI model, model version, future updates, system instructions, or prompt design. These findings should be interpreted as documented observations from this workflow rather than universal conclusions.
Repeatability
This experiment was conducted in a single documented conversation using three prompts about AI slop. Repeating the same prompt sequence with different AI models, model versions, or testing conditions may produce different results.
Evidence
Evidence presented below consists of screenshots captured during the documented testing session.
Figure 1: Response generated using the generic prompt “Explain AI Slop.”
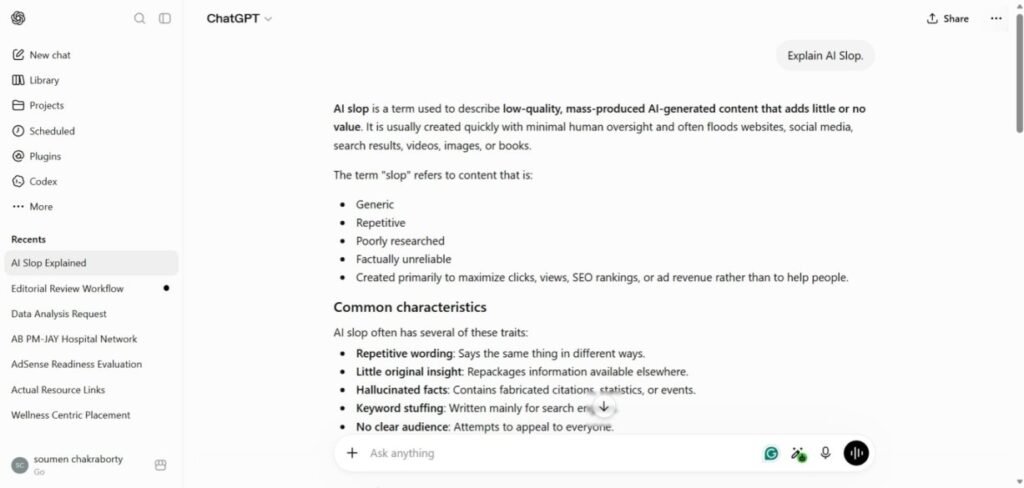
Figure 2: Response generated using the prompt “Explain AI Slop with real examples.”
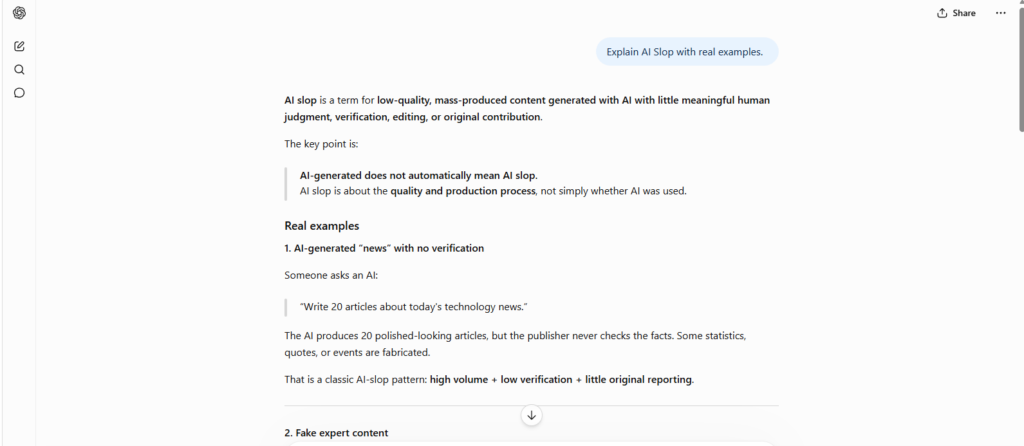
Figure 3: Response generated using the prompt “Explain AI Slop for SEO writers who publish AI-assisted content.”
Why this matters
This documented observation illustrates how adding task, example, and audience context can change the relevance and practical utility of AI-generated responses under the tested conditions.
Related Articles
This experiment supports the findings discussed in:
Publication Information
Published:
27 July 2026
Last Updated:
20 August 2026
Version:
1.0
Editorial Review:
Completed
Editorial Note
The prompts and outputs used in this experiment were generated through actual testing. The observations and research summary were reviewed before publication to ensure they accurately reflect the documented outputs and do not extend beyond the evidence presented.
No AI-generated content has been presented as independent evidence without corresponding human review and documented interpretation.
Next Experiment
EXP-002: Instruction Retention Test (EXP-002) | AI Behavior Research