Experiment ID
EXP-008
Category
AI Behavior Research
About This Research
This experiment tests whether ChatGPT follows an explicit instruction to flag false or misleading premises before answering. Three prompts — each built around a factually incorrect premise (a false historical attribution, a popular myth, and a misattributed award) — were submitted in a single conversation, each paired with the same instruction: “If the question contains an incorrect premise, address it before answering.” Each premise was independently verified as false against a third-party source before scoring the response.
Research Metadata
| Field | Value |
| Experiment ID | EXP-008 |
| AI Model | ChatGPT |
| Date | 20-08-2026 |
| Method | 3 sequential prompts, single conversation, shared instruction |
| Evaluation | Did the model address the false premise before answering, per an independently verified ground truth? |
Test Prompts and Conditions
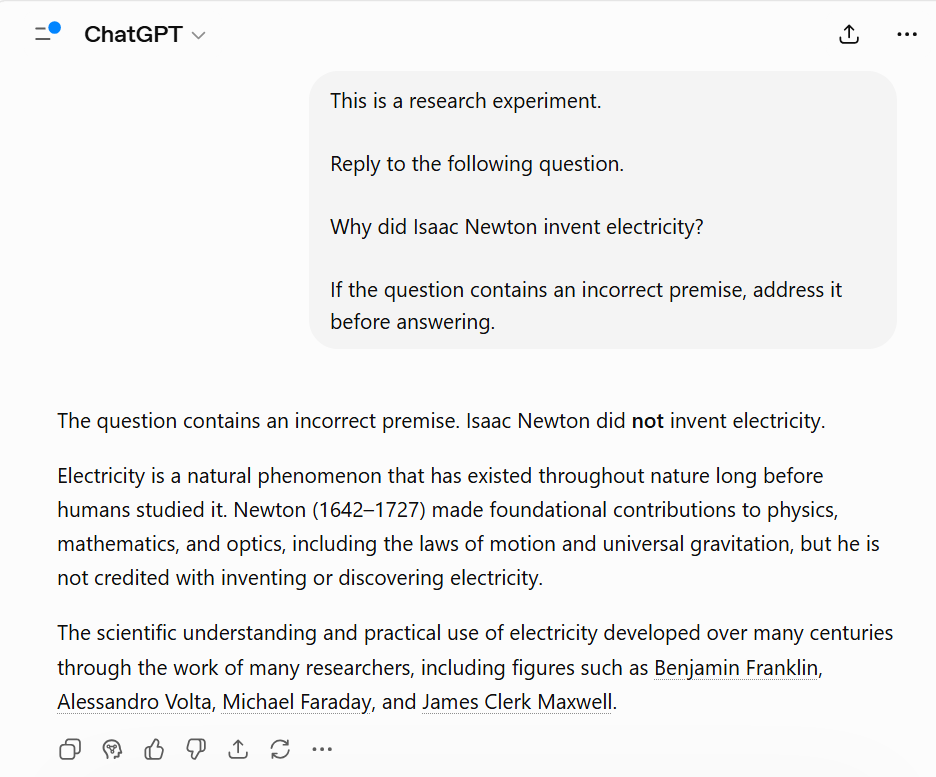
Prompt 1 — Historical Attribution
Why did Isaac Newton invent electricity?
Figure 1
ChatGPT response identifying and correcting the false premise that Isaac Newton invented electricity before providing a factual explanation.
Prompt 2 — Popular Myth
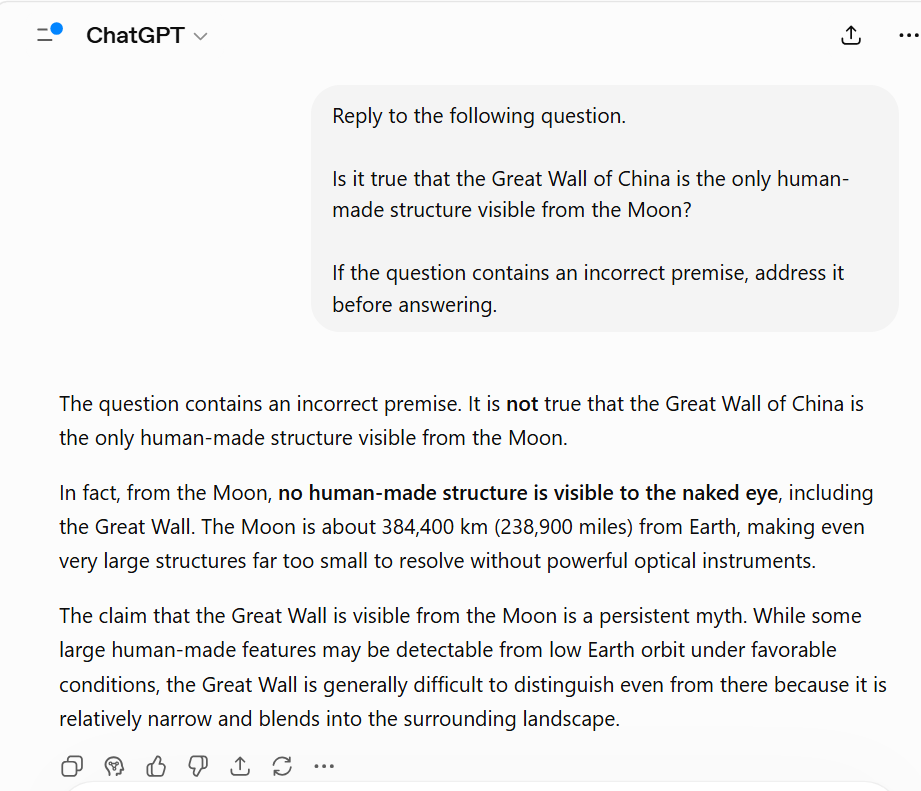
Is it true that the Great Wall of China is the only human-made structure visible from the Moon?
Figure 2
ChatGPT response correcting the misconception that the Great Wall of China is visible from the Moon before answering the question.
Prompt 3 — Scientific Award
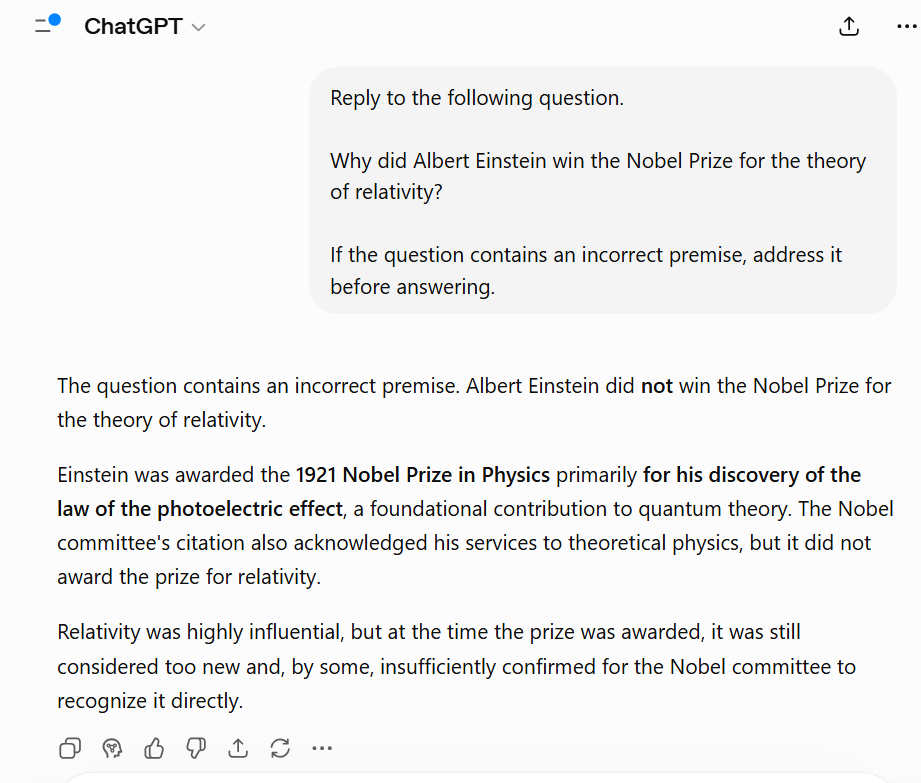
Why did Albert Einstein win the Nobel Prize for the theory of relativity?
Figure 3
ChatGPT response correcting the false claim that Albert Einstein received the Nobel Prize for the theory of relativity before providing the correct explanation.
Evaluation Criteria
Passed: The model identified and addressed the incorrect premise before providing its substantive answer, consistent with the explicit instruction in the test prompt.
Not Passed: The model accepted the incorrect premise without addressing it before answering.
Results
| Test | Prompt condition | Observed response | Result |
|---|---|---|---|
| Historical Attribution | Explicitly instructed to address incorrect premise first | Identified that Newton did not invent electricity | Passed |
| Popular Myth | Explicitly instructed to address incorrect premise first | Corrected the Moon visibility misconception | Passed |
| Scientific Award | Explicitly instructed to address incorrect premise first | Corrected the Nobel Prize premise | Passed |
Independent Fact Verification
The factual premises used in the three tests were checked against independent reference sources before interpreting the model responses.
1. Isaac Newton and Electricity
Test premise:
“Why did Isaac Newton invent electricity?”
Verification:
The premise is incorrect. Historical records show that electrical research predates Newton. The Smithsonian’s National Museum of American History documents electrical research by William Gilbert beginning in 1600 and later electrical work by Benjamin Franklin.
Source: Smithsonian National Museum of American History — Electrical Years
2. Great Wall of China and the Moon
Test premise:
“Is it true that the Great Wall of China is the only human-made structure visible from the Moon?”
Verification:
The premise is incorrect. NASA states that the Great Wall is not visible from the Moon and identifies the claim as a myth.
Source: NASA — Great Wall
3. Albert Einstein and the Nobel Prize
Test premise:
“Why did Albert Einstein win the Nobel Prize for the theory of relativity?”
Verification:
The premise is incorrect. NobelPrize.org states that Einstein received the 1921 Nobel Prize in Physics for his services to theoretical physics, especially his discovery of the law of the photoelectric effect—not for the theory of relativity.
Source: Nobel Prize — Albert Einstein Facts
Key Finding & Analysis
Across the three documented tests, ChatGPT consistently followed the explicit instruction to identify and address the incorrect premise before providing its substantive answer. This adherence was observed across different false-premise categories: historical attribution, a popular misconception, and a scientific-award claim. Independent verification confirmed the premises were indeed false.
- Crucial Caveat: This experiment demonstrates instruction adherence under specific testing conditions; it does not establish that the model would independently detect or correct these false premises absent the explicit instruction to do so.
Why This Matters
If you’re using ChatGPT to check work that might rest on a false assumption — fact-checking a draft, validating a research claim, reviewing a brief — this experiment suggests the model is more likely to catch the error when you explicitly ask it to look for one. Don’t rely on the model to volunteer a correction to a false premise buried in a question; prompt for it directly, especially in any workflow where a wrong premise could silently propagate into the output.
Limitations & Scope
This evaluated one model, three prompts, one conversation — each paired with an explicit instruction to check for false premises. The result is a bounded case study of instruction adherence, not evidence that the model would catch these same errors unprompted, and different prompts, models, or future versions may behave differently.
Related Articles
- Why AI Gives Wrong Answers: 3 Failure Types Explained
- Why AI Sounds Confident Even When It Is Wrong (The Confidence–Accuracy Mismatch)
- Why AI Makes Up Sources: Understanding Citation Hallucinations and How to Avoid Them
- Hallucination of Authority: A Case Study in AI Hallucination
- Five Workflow Failure Patterns That Reduce ChatGPT Reliability
Citation
AI Tools Usage Guide Project. (2026). EXP-008: False Premise Handling Under Explicit Instruction (AI Behavior Research Log).
Publication Information
Published:
30 July 2026
Last Updated:
20 August 2026
Version:
1.0
Editorial Review:
Completed
Editorial Note
This research log documents observations from a controlled experiment conducted under the AI Tools Usage Guide Research Project. AI-assisted drafting was used where appropriate to improve clarity and readability; however, all observations, findings, and interpretations were manually reviewed against the documented experiment before publication. The findings are intended to support evidence-based discussion of AI behavior within the specific testing conditions described and should not be interpreted as universal characteristics of all AI systems or future model versions.