Quick Answer: AI can give wrong answers for several different reasons, including outdated knowledge, missing context, hallucinated information, and data or metric-semantics errors. Identifying the failure type can be more useful than simply switching to another AI model, because different failure types require different fixes.
Key Takeaway: This guide distinguishes four important AI failure types: missing context, outdated information, hallucinated content, and data or metric-semantics errors. The documented experiments provide evidence for specific aspects of the failure types that were tested under the conditions described in this article.
The Problem Users Often Misdiagnose
Why AI gives wrong answers can be confusing in everyday AI use, especially when different failure types produce similar-looking responses. A common mistake is to assume that every wrong AI answer is a hallucination.
When AI gives a wrong answer, users may assume the model “hallucinated.”
The guide focuses on four failure types that can look similar to users: knowledge-cutoff errors, missing-context errors, hallucinated or unsupported information, and data or metric-semantics errors.
Failure Type 1: Knowledge Cutoff Errors
What it is
The underlying model weights do not contain information beyond the training cutoff, although some systems can supplement this through web retrieval or external tools.
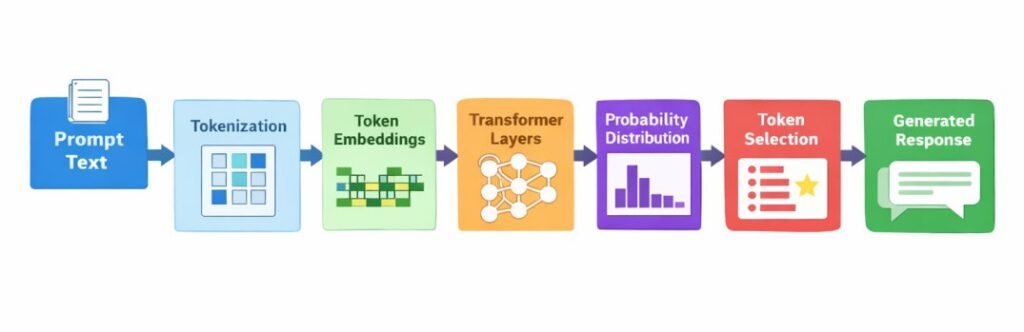
When you ask about something that changed after the training cutoff, a model may still answer even when its underlying training data does not contain the newer information. Without current retrieval or another reliable source, the response may rely on older learned information and therefore be out of date.
What this means in practice
A model’s knowledge may not reflect the most recent changes to a tool, product, or technical subject. When information may have changed since the model’s available knowledge, treat the answer as a starting point rather than current verification.
For recent releases, feature changes, version information, or other time-sensitive details, check the relevant current source before relying on the answer.
Why this happens
The model generates responses from learned patterns and the context available at generation time. If newer information is not available through the model or an enabled retrieval source, the response may rely on older learned information even when the underlying facts have changed.
Practical verification approach
For time-sensitive questions, state the relevant date or time period explicitly and verify the answer against a current, reliable source. A temporal reference can make the requested time frame clearer, but it does not by itself establish that the model has current information.
Instead of:
“What are the latest AI tools for content teams?”
Use:
“What AI tools were commonly used by content
teams as of early 2025? I will verify current
availability separately.”
Evidence boundary: The documented experiments referenced in this article did not independently benchmark knowledge-cutoff behavior or establish that temporal anchoring prevents outdated answers. This section provides practical guidance for handling time-sensitive information rather than reporting a controlled experiment.
If current accuracy matters, provide the source document directly — do not rely on the model’s internal memory for time-sensitive topics.
Failure Type 2: Missing Context Errors
What it is
When a prompt is vague, the model may fill in missing context based on patterns learned during training and the context available in the prompt. This can produce answers that are technically plausible — but wrong for your specific situation.
What I observed in testing
Documented Spot-Check: EXP-001 (Prompt vs. Output) Here is the exact side-by-side comparison from our testing session that demonstrates this assumption gap:
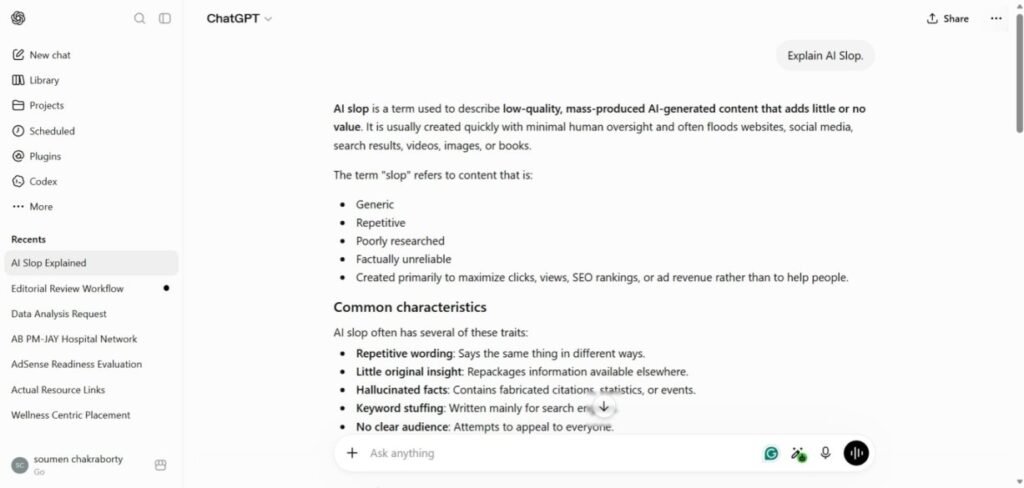
- Prompt 1 (Vague): “Explain AI Slop.”
- AI Output: Provided a broad, dictionary-style overview of low-quality AI writing, applicable to anyone.
- Prompt 2 (Highly Contextual): “Explain AI Slop for SEO writers who publish AI-assisted content.”
- AI Output: Skipped the generic overview and immediately provided workflow-oriented guidance, specifically addressing search engine penalties, content scaling risks, and editing frameworks.
The Prompt Alignment Problem

What the test showed: Adding audience and task-specific context produced a more focused and workflow-oriented response in this test. This suggests that clearer constraints can reduce the amount of context the model has to infer, but the test does not establish this as a general mechanism across AI systems.
The fix
Define the who, what, when, and where explicitly:
Instead of:
“Summarize the key points.”
Use:
“Summarize the key operational findings
for a technical audience familiar with
AI prompt testing. Focus on workflow
implications, not general observations.”
Research Evidence: EXP-001 — Prompt Specificity Test
Failure Type 3: AI Hallucination
What is AI hallucination?
Hallucination occurs when a model generates unsupported or fabricated information and presents it as if it were reliable. This can include citations that do not exist, statistics that were never published, or events that never happened.
A hallucination is different from a stale-data error: stale answers rely on information that was once valid but is now outdated, while hallucinations introduce unsupported or fabricated information. The fix also differs—stale information requires current verified sources, while hallucinations require claim verification and stronger grounding.
Across the prompt tests conducted for this article, hallucination was observed alongside missing-context and knowledge-cutoff failures.
What I observed in testing
Documented Spot-Check: EXP-004 (Fabricated Citation) In our citation-reliability test, we asked the model to provide academic sources for a specific claim.
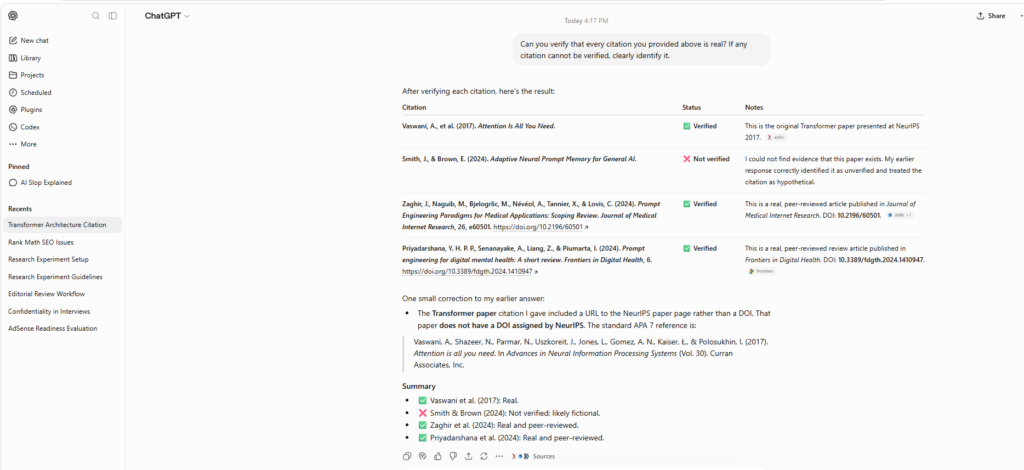
The Model’s Output: The model generated a highly convincing reference: “Smith, L. & Brown, C. (2024). Adaptive Neural Prompt Memory for General AI.
The Reality: The formatting was perfect, the journal name was real, but the article and authors were completely fabricated. This test shows why AI-generated academic citations should be independently verified rather than treated as verified sources.
| Failure Type | What the Problem Looks Like | Practical Check |
|---|---|---|
| Knowledge Cutoff | Information may be outdated | Check the relevant date and current source |
| Missing Context | The answer may not fit the situation because important context was missing or unclear | Check whether the necessary context was provided |
| Unsupported/Fabricated Information | Claims, citations, statistics, or details may not be verifiable | Verify the claims and sources independently |
| Data / Metric-Semantics Error | The result may use the wrong metric definition, fields, filters, business rules, or calculation | Verify the metric definition and underlying data operation |
Why it happens
Generative models are designed to produce fluent, coherent responses from learned patterns and the context available to them. When the information needed to answer a question is missing, the model may still generate a plausible-sounding response instead of reliably identifying the missing information or refusing to answer.
Because citations, statistics, and named sources follow familiar textual patterns, a model can sometimes generate plausible-looking references even when the underlying information is unsupported.
The fix
Add an ignorance constraint to your prompt:
“If you do not have a verified source for
this claim, state ‘Source unavailable’
rather than providing an estimated reference.
Do not generate citations from memory.”
For high-stakes outputs — anything involving specific statistics, named sources, or factual claims — verify independently before publishing or acting on the information.
Failure Type 4: Data / Metric-Semantics Errors
What it is
An AI data tool can produce an incorrect business metric even when the relevant data is available. The problem may be that the system misunderstood what the metric means, selected the wrong fields or dimensions, applied the wrong filters or business rules, or translated the business question into the wrong calculation or data operation.
This is different from a missing-context failure. With missing context, important information needed to answer the question was not supplied. With a data or metric-semantics error, the relevant data may be available, but the business meaning or required calculation can still be interpreted incorrectly.
For example, consider the question:
“What are our best-selling products?”
Depending on the business definition, “best-selling” could refer to units sold, revenue, number of orders, or another defined measure. If the AI selects a different measure from the one the business intends, the resulting metric can look plausible while still answering the wrong question.
Why it happens
Business questions are often less precise than the underlying data operations needed to answer them. A metric may depend on specific fields, dimensions, filters, joins, aggregation rules, or business definitions that are not obvious from the natural-language question alone.
An AI system can therefore produce a technically plausible result while using the wrong interpretation of the business metric.
The fix
Before relying on an AI-generated business metric, verify:
- What exactly does the metric mean?
- Which fields or dimensions are being used?
- Which filters or business rules are being applied?
- How is the metric calculated or aggregated?
For important business decisions, verify the metric definition and the underlying data operation rather than checking only whether the final number looks reasonable.
The Verification Workflow
o fix a wrong AI answer, first identify why it failed. Check whether the answer is outdated, based on missing context, contains unsupported information, or uses the wrong metric definition or calculation—then apply the fix that matches that failure type.
For any AI output where accuracy matters:
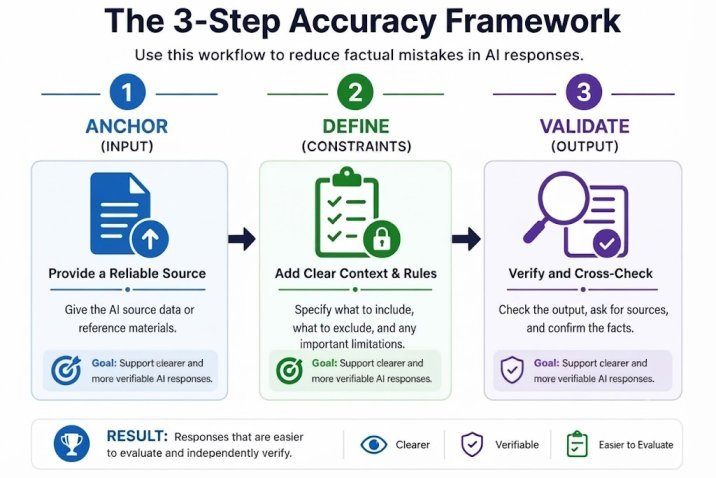
The 4-Step Verification Workflow
Step 1 — Identify the failure type
Does the output appear outdated, based on missing context, unsupported or fabricated, or inconsistent with the intended metric definition or calculation? Match the symptom to the failure type above.
Step 2 — Apply the right fix
- Outdated information → check the relevant date and provide a current source
- Missing context → add the necessary context, constraints, audience, or task requirements
- Unsupported or fabricated information → verify the claim or source independently; use an ignorance constraint where appropriate
- Data / metric-semantics error → verify the metric definition, fields, filters, business rules, and calculation
Step 3 — Run a consistency check
When useful, run the same prompt multiple times under the same conditions.
If outputs differ substantially in structure, facts, or conclusions, review whether the prompt lacks sufficient constraints, context, or a stable evaluation condition.
Similar outputs across repeated runs can provide additional evidence of response consistency, but consistency alone does not establish factual accuracy.
Step 4 — Verify high-stakes claims independently
Do not rely on AI output alone for statistics, citations, legal information, time-sensitive facts, or other claims where accuracy matters. Verify the relevant claim against an appropriate primary or reliable source before publishing or acting on it.
A Pattern Observed Across the Prompt Tests
Across the prompt tests documented in this research, clearer constraints and reduced ambiguity were associated with more focused responses. In several tests, adding specific task requirements appeared more useful than adding broad instructions that increased prompt length.
These observations suggest that prompt quality depends not only on how much information is provided, but also on how clearly the task, constraints, and expected output are specified.
When Factual AI Use Requires Extra Verification
Based on the prompt tests conducted here, these task types showed higher verification risk because the information can change quickly, depends on external sources, or requires a source that the model may not have available:
❌ Real-time pricing or market data
❌ Current legal or regulatory requirements
❌ Recent product versions or release notes
❌ Specific statistics from named studies
(without providing the study directly)
❌ Any claim requiring a verified source
you cannot independently check
For these tasks, provide the source document and instruct the model to extract only — not to generate from memory.
Limitations
Evidence Boundary
The experiments documented here are observations from limited ChatGPT testing sessions conducted under specific prompts and conditions. They illustrate the failure-handling patterns observed in these tests, but they do not establish how frequently these failures occur across AI systems or constitute controlled benchmark results.
Conclusion
The documented testing examined several different failure-handling patterns, including outdated-information risks, missing context, unsupported information, and data or metric-semantics errors.
The practical takeaway is that diagnosing why an answer may be wrong can help determine the appropriate verification or correction step. For factual claims, verification remains necessary regardless of model quality.
Key Takeaways
- Not every incorrect AI answer is a hallucination.
- Missing context can often be addressed by providing the information or constraints the model needs, without changing the model itself.
- Verify factual claims whenever accuracy matters.
Research Summary
This article draws on documented AI behavior experiments conducted under the AI Tools Usage Guide research workflow. The experiments examined prompt specificity, ambiguity resolution, and citation reliability using documented ChatGPT testing sessions. Findings are based on observed responses under the specific prompts and testing conditions described in the linked experiments.
| Research Variable | Details |
|---|---|
| AI Model Tested | ChatGPT |
| Experiments Referenced | EXP-001, EXP-003, EXP-004, EXP-007 |
| Prompt Testing | Structured prompt variations |
| Evaluation Focus | Prompt specificity, ambiguity resolution, citation reliability |
| Evidence Type | Documented conversation screenshots and observational analysis |
| Study Limitation | Single-model, limited documented sessions |
Key Finding:
The documented prompt tests illustrate how missing context, citation handling, and unsupported information can require different verification or corrective approaches.
Frequently Asked Questions
Does the AI’s “Temperature” setting affect the failure type?
Yes. Temperature can affect the variability of model outputs, but this article did not independently test different temperature settings. Therefore, the documented experiments here do not establish how temperature changes hallucination risk.
Are these four failure types the only ways AI can be wrong?
No. Knowledge-cutoff, missing context, hallucinations or unsupported information, and data or metric-semantics errors are important failure modes, but they are not the only ways AI can produce problematic answers.
Will giving the AI a web link prevent outdated knowledge?
Not always. Simply pasting a link doesn’t guarantee the AI will successfully retrieve and process the current page content. If the retrieval fails, the model may silently fall back on its outdated training data (Failure Type 1). Ask the model to quote the relevant passage from the provided source when source verification matters. Treat the quotation as an additional verification step, not as proof that the model retrieved or interpreted the source correctly.
References
- Brown et al. (2020). Language Models are Few-Shot Learners. https://arxiv.org/abs/2005.14165
- Vaswani et al. (2017). Attention Is All You Need. https://arxiv.org/abs/1706.03762
- OpenAI (2023). GPT-4 Technical Report. https://arxiv.org/abs/2303.08774
- Google Search (2023). AI-generated content guidance. https://developers.google.com/search/blog/2023/02/google-search-and-ai-content
If you’re dealing with this problem in a real AI workflow, an AI reliability investigation can examine the available evidence and identify which explanations are actually supported.
Discuss an AI Reliability Investigation →
- The 4 Prompting Moves That Fix Generic AI Output - September 12, 2026
- How to Evaluate AI Answer Reliability: A 7-Step Verification Framework - August 9, 2026
- AI Memory vs. Context Window: Why Most People Confuse Them (And Why It Matters) - July 23, 2026