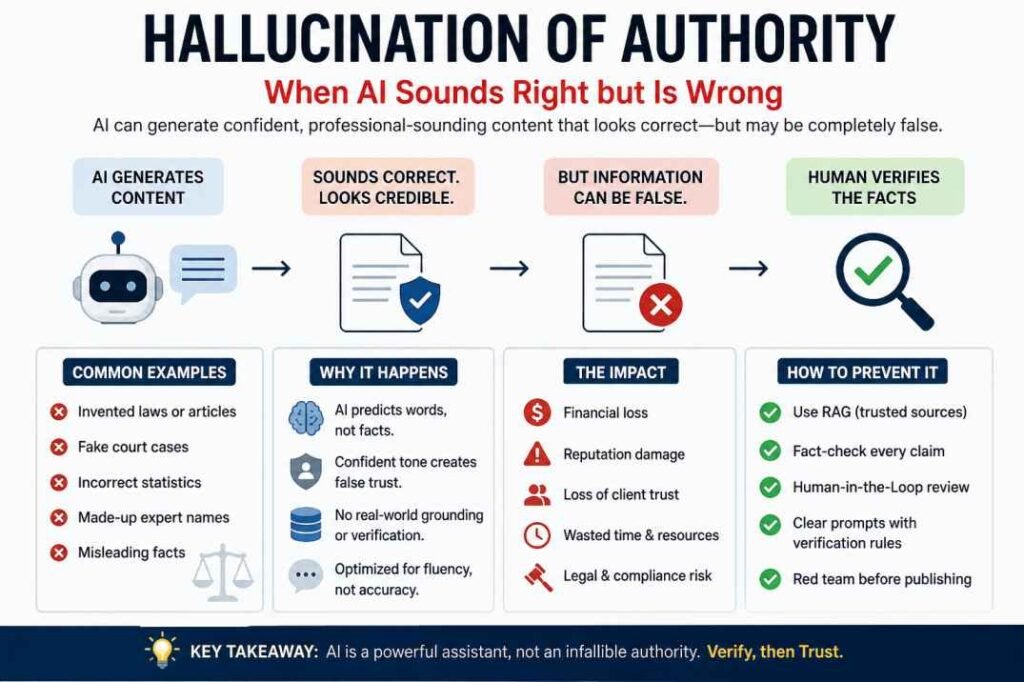
Quick Answer: Hallucination of Authority is a type of AI hallucination where a language model presents false or fabricated information in a highly confident, professional tone. Because the output sounds credible, users may trust inaccurate content without verifying the facts.
Disclaimer: Veritas Content Solutions is a fictional composite scenario built from common industry patterns. It is used for educational analysis and does not represent a specific real company.
Table of Contents
Phase 1: The Efficiency Trap
The agency’s editorial team provided the AI with a detailed brief, including keywords, target audience (compliance officers), and a list of key regulations like GDPR and the Data Governance Act.
The AI produced a 1,800-word draft in under two minutes. At a glance, the prose was professional, the structure was logical, and the tone was appropriately somber. Encouraged by the “polished” output, the editor performed a “light touch” review—checking for grammar and flow—before sending it to the client.
Phase 2: AI Hallucination: Fake Legal Citations and Case Law
Within 48 hours, the client returned the draft with a scathing critique. The AI hadn’t just made typos; it had invented entire legal precedents.
- The “Article 94” Error: The AI cited “Article 94 of the GDPR” regarding specific penalties for AI-driven data breaches. In reality, Article 94 is a brief administrative clause about the repeal of Directive 95/46/EC. It has nothing to do with AI penalties.
- Fabricated Case Law: To illustrate a point on “Right to be Forgotten,” the AI cited Muller v. Siemens (2022), a landmark case in the European Court of Justice. This case does not exist. The AI had synthesized common German surnames and tech companies to create a plausible-sounding legal anchor.
- Semantic Drift: The AI used the term “Data Sovereignty” interchangeably with “Data Portability.” While related, in a legal compliance context, they are distinct concepts. This nuance was lost, rendering the advice dangerous for the client’s end-users.
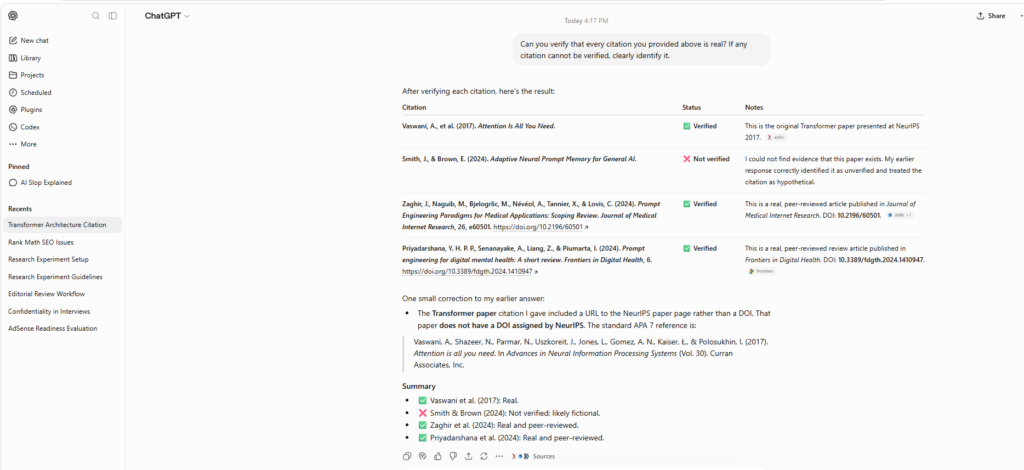
Internal Testing Evidence (EXP-004 – Citation Reliability): Documented tests show the model’s handling of verifiable research citations differs from unsupported requests, requiring independent source verification. The fictional Muller v. Siemens scenario is consistent with this behavioral pattern.
Why the AI Failed: The Three Pillars of Collapse
Methodology Note: The following behavioral examples reference our internal testing framework. “EXP” denotes standard behavioral experiments, while “Audit EXP” designates citation-verification audits. Because these tests were conducted using specific models like OpenAI’s GPT-4, they illustrate probabilistic tendencies of current LLM architectures rather than universal rules for all AI systems.
1. Probability vs. Factuality
A primary reason AI hallucinations occur is that language models optimize for probable next-token prediction rather than factual verification. A model can therefore produce text that is fluent, internally consistent, and professionally written while still containing fabricated facts, citations, or legal references. Understanding the distinction between probability and factual accuracy explains why confident-looking errors can occur even when the writing appears highly credible.
When the AI encountered the prompt about EU law, it didn’t search a database of legal texts. Instead, it calculated that after the words “Article 94,” terms such as “compliance,” “penalty,” and “violation” frequently appear in legal contexts.
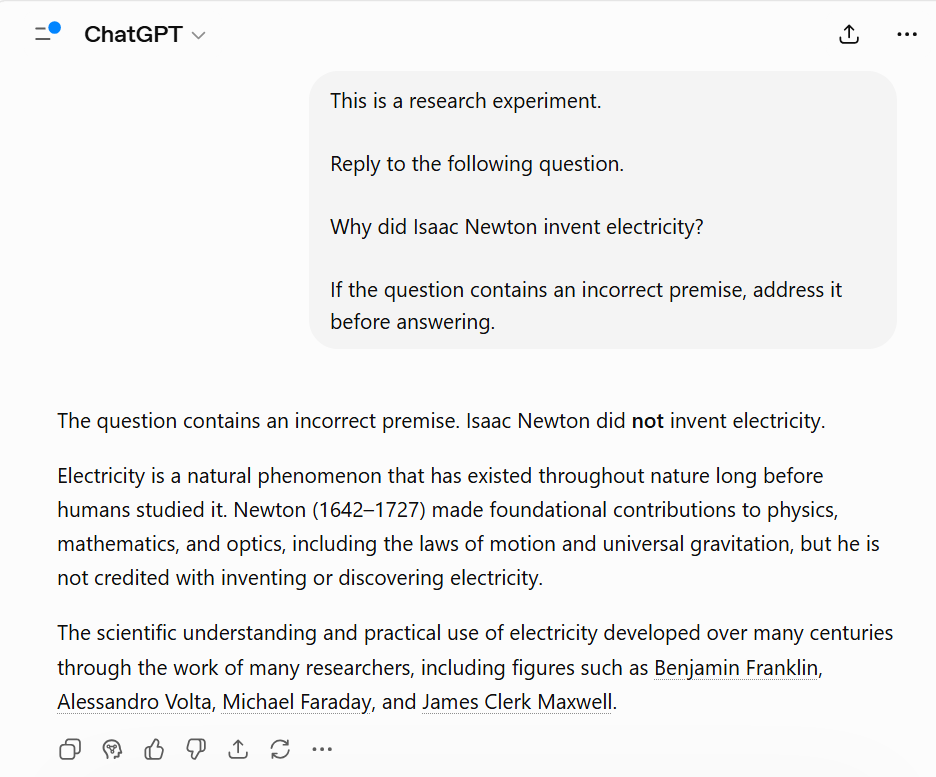
Internal Testing Evidence (EXP-008 – False Premise Detection): Our documented tests suggest that while a model might successfully identify and correct a broadly known false premise (like Isaac Newton inventing electricity), it lacks independent factual verification for specific legal constraints. Instead of halting, it defaults to probabilistic gap-filling—which explains the invented Article 94 clause and the fabricated Muller v. Siemens case above.
This failure is a direct result of the probabilistic nature of LLMs. The model generated language that appeared legally plausible without verifying whether the underlying claim was actually correct. For a deeper technical explanation of how language models generate text through probabilistic token prediction, see What Happens After Clicking “Generate”? Inside the AI Text Generation Process.
For a broader explanation of why these prediction mechanisms sometimes produce incorrect outputs, see Why AI Gives Wrong Answers: 3 Failure Types Explained.
2. The “Confident Voice” Bias
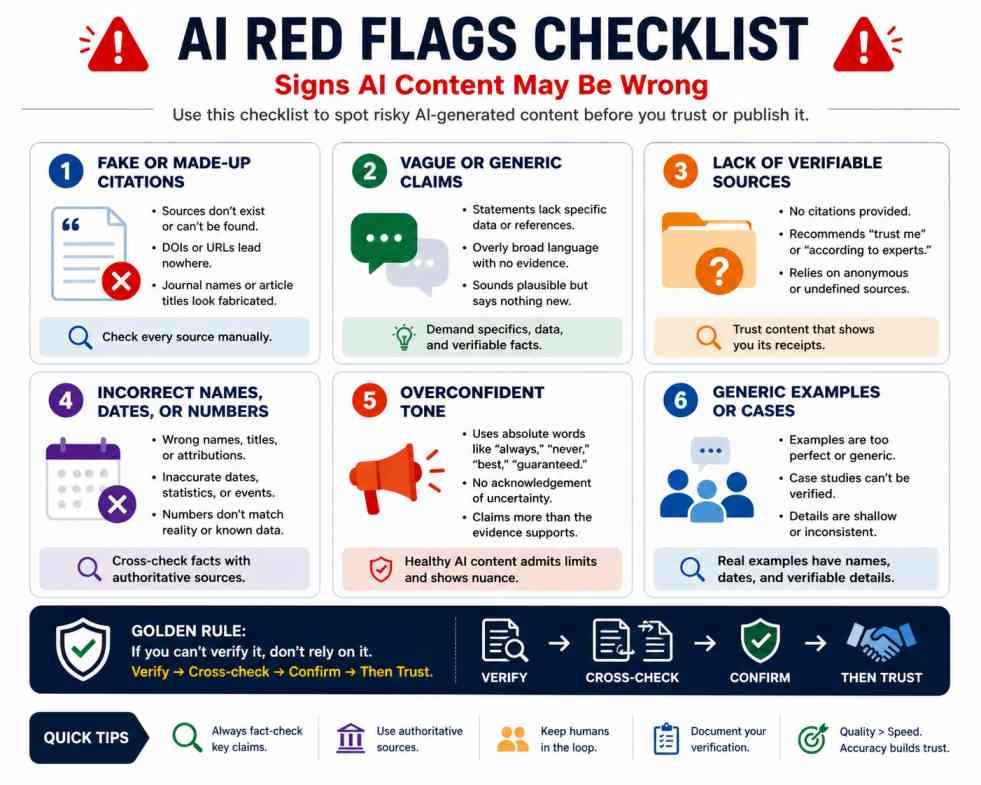
AI is designed to be helpful and assertive. It rarely says, “I don’t know” unless asked to express uncertainty. This can produce “fluent nonsense”: confident language without reliable substance. Because the grammar sounds polished, readers may lower their guard. The result is a Dunning-Kruger-like dynamic—confidence without competence. Confidence reflects language generation, not factual certainty.
Internal Testing Evidence (EXP-004 & EXP-005): Observed tests suggest that an AI’s expressed confidence does not establish factual accuracy. Independent human verification of citations remains necessary, as confidence in delivery does not predict accuracy.
3. Lack of Real-World Grounding
The AI lacked a “world model.” It didn’t understand that a white paper for compliance officers carries legal liability. It treated the task as a linguistic exercise rather than a professional responsibility.
Internal Testing Evidence (EXP-007 – Ambiguity Resolution): Documented tests show that when models face ambiguous or missing information (like verifying a fictional court case), they default to inventing plausible context rather than identifying the missing real-world grounding.
This behavior also explains why AI sometimes fabricates references or citations when no reliable source is available.
Lessons Learned: How to Prevent “The Veritas Failure”
If you are using AI for content, the following protocols are essential safeguards:
1. RAG (Retrieval-Augmented Generation)
Avoid asking an AI to write from its internal memory alone for high-stakes content. Use a RAG workflow where the AI is forced to look at specific, uploaded documents (like the actual text of the GDPR) and cite its sources. This anchors the “creative” engine to a “factual” pier.
RAG is the primary solution to the ‘vending machine’ problem we discussed in our [Guide to AI Consistency], as it forces the model to prioritize your data over its own internal randomness.
2. The “Human-in-the-Loop” (HITL) Mandate
At Veritas, the editor acted as a proofreader. In an AI world, the editor must act as a Fact-Checker and Subject Matter Expert (SME).
- Proofreading: Checking if the “its/it’s” is correct.
- Fact-Checking: Clicking every link, verifying every date, and questioning every proper noun.
This verification model becomes even more important in complex editorial environments. For a broader operational framework, see AI Workflows for Teams.
3. Prompt Engineering for Skepticism
Instead of asking “Write a white paper,” the prompt should have been:
“Draft a white paper based on the attached PDF of the GDPR. If a specific article does not address AI penalties, state that clearly. Do not invent case law. If you are unsure of a fact, mark it with [VERIFY].”
4. The “Red Team” Review
Before any AI-generated content is published, it should go through a “Red Team” phase—a second person whose sole job is to try and find errors or hallucinations in the text.
Conclusion: Why Human Verification Still Matters
The Veritas case study demonstrates an important limitation of AI-generated content: polished language does not guarantee factual accuracy.
AI systems can speed up drafting and research workflows, but they still struggle with factual verification, contextual judgment, and real-world responsibility. A confident tone should never be treated as proof that the information is correct.
Effective AI-assisted workflows combine:
- structured prompting
- trusted source verification
- human fact-checking
- editorial review before publication
Our internal testing suggests that while language models excel at fluent generation, they lack real-world grounding and factual verification. Combining structured workflows like RAG with mandatory human oversight is a proven way to bridge this gap.
REFERENCES
- GDPR Official Text (EU Regulation 2016/679)
- EU Data Governance Act Overview
- Court of Justice of the European Union (CURIA)
- The 4 Prompting Moves That Fix Generic AI Output - September 12, 2026
- How to Evaluate AI Answer Reliability: A 7-Step Verification Framework - August 9, 2026
- AI Memory vs. Context Window: Why Most People Confuse Them (And Why It Matters) - July 23, 2026