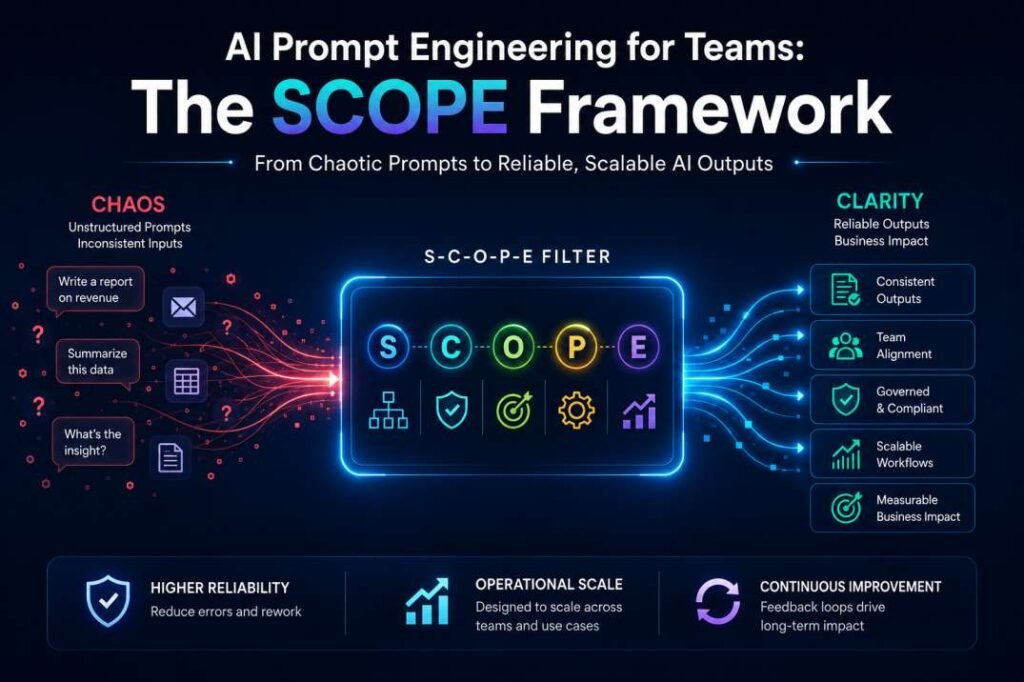
Quick Answer: AI Prompt Engineering for Teams is the process of creating structured prompting systems that help multiple employees generate consistent, reliable, and scalable AI outputs.
Instead of relying on personal prompting habits, teams use standardized templates, workflow rules, and review systems to improve output quality and reduce structured inconsistency.
Introduction
When AI adoption expands across departments, organizations run into the same bottleneck every time: access to a powerful model doesn’t guarantee consistent output. This guide breaks down why that happens and how a structured prompting system — the SCOPE framework — fixes it, backed by controlled tests we ran ourselves (EXP-001 through EXP-003, PIPE-006, PIPE-009).
Table of Contents
Why Individual Prompting Fails Inside Teams
Most users interact with AI reactively, entering a prompt and expecting a reliable result without a defined workflow structure.
- Personal Use: You know your internal context. Even a fragmented prompt works because you can mentally fill in the gaps.
- Team Operations: Every team member has a different skill level and baseline context. Without a structured framework, outputs instantly fracture into inconsistent tones, formats, and depths.
Illustrative scenario: Picture three employees completing the same AI-assisted task, each using their own prompting habits. Even with the same objective, you’d expect the outputs to differ in tone, formatting, and factual depth — not because the model is inconsistent, but because the inputs were.
The Decision Rule: If the same task run by two different employees produces outputs that need materially different edits before use, that’s a structure problem — not a skill problem. Fix the prompt template, not the person.
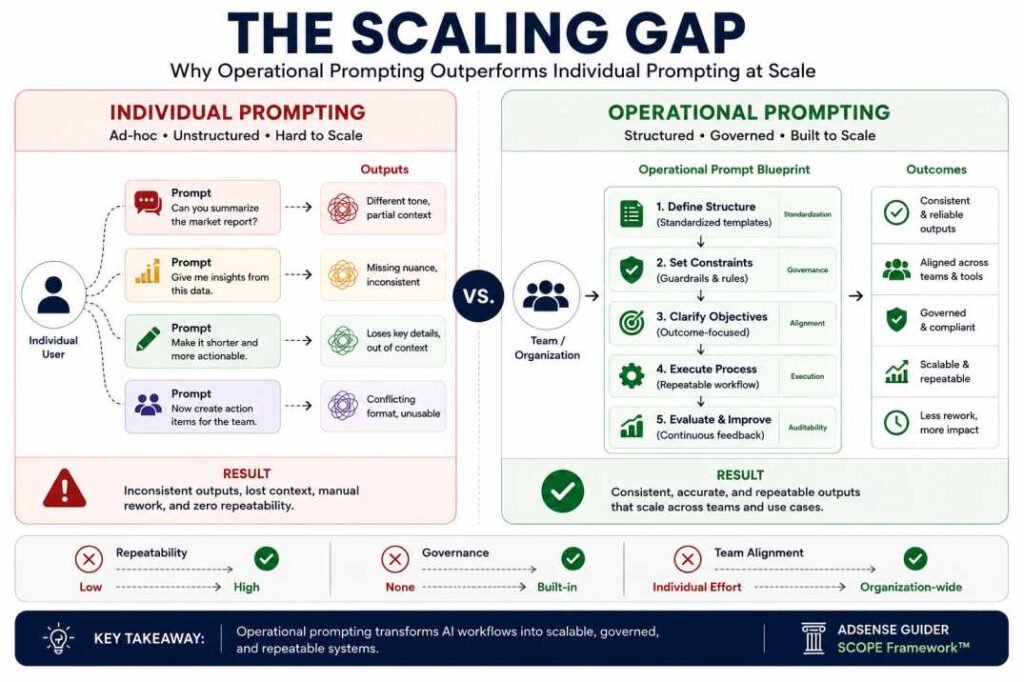
Well-designed prompts reduce ambiguity before work enters a team workflow. Instead of examining workflow execution, this guide focuses on how standardized prompt structures improve consistency, governance, and repeatable AI outputs across multiple users.
The SCOPE Framework: Engineering Repeatable Logic
To achieve consistent AI outputs across multiple employees, organizations need more than well-written prompts—they need a repeatable prompting structure. The SCOPE Framework provides a standardized template that reduces unnecessary variation while improving consistency, governance, and operational reliability.
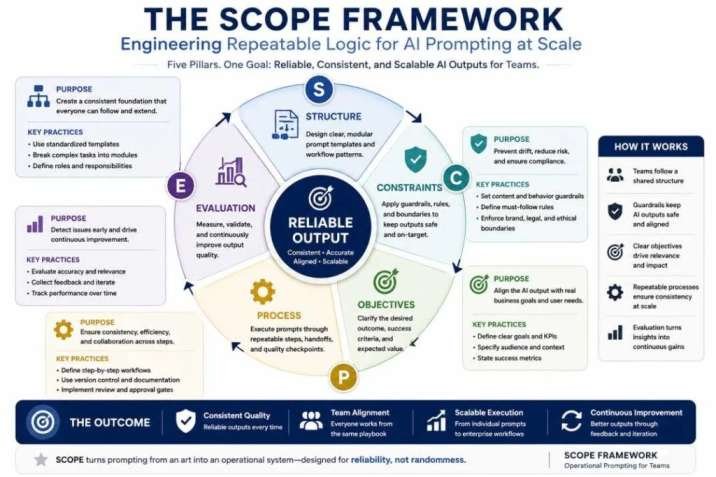
Starter Operational Template
Role: [Department Role]
Goal: [Business Objective]
Constraints: [Word limits, compliance rules, style requirements]
Process: [Step-by-step workflow]
Output Format: [Markdown, table, JSON, report]
Evaluation: [Accuracy, completeness, policy compliance]
Weak Prompt
“Write a report about customer complaints.”
Operational Prompt
“You are a Senior Customer Operations Analyst. Review the complaint summaries, identify the three most common operational failures, and present the findings in bullet points for executive review. Keep the response under 250 words.”
S — System Role
What we found (EXP-001): When we tested a broad prompt like “Write a report about customer complaints,” the model produced a generic, low-utility definition. Adding a role and audience — “You are a Senior Customer Operations Analyst responsible for summarizing customer complaints for executive review” — shifted the same request into a structured, executive-ready breakdown of operational failures. [Read the full EXP-001 writeup →]
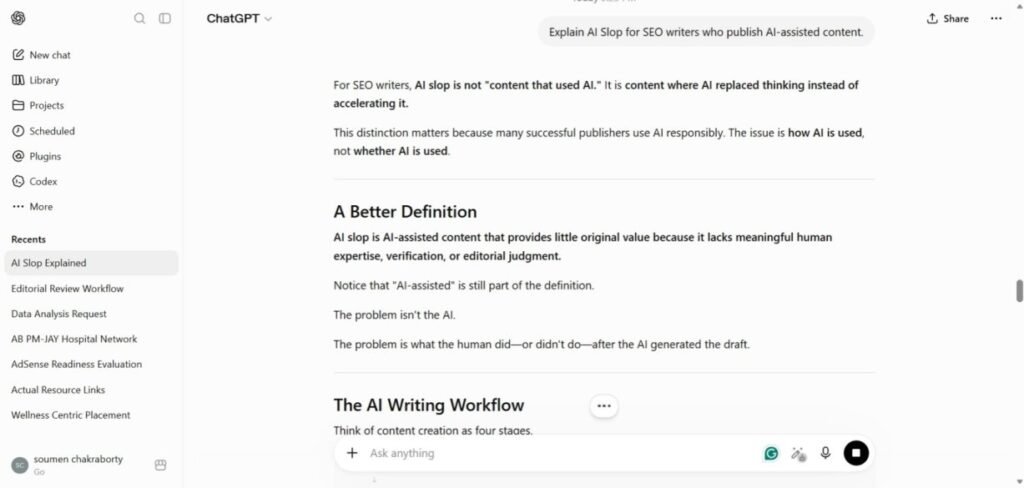
Why it matters for teams: A role isn’t decoration — it’s the variable that determined whether the output was usable or not in our test. Define the AI’s operational role before assigning the task, so every team member starts from the same shared perspective instead of whichever framing they happen to think of.
C — Constraints
Specify mandatory boundaries before generation, including word limits, compliance requirements, prohibited content, or style rules. Shared constraints reduce variation between employees.
Example
Do not include unsupported claims
- No technical jargon
- Maintain a neutral tone
- Maximum 300 words
O — Output Format
Define the required structure before generation, such as Markdown, tables, JSON, or executive summaries. Consistent formatting allows outputs to move directly into business workflows with minimal editing.
P — Process Logic
Break complex work into sequential steps rather than asking the model to complete everything at once.
Example
- Analyze the source information.
- Identify the key findings.
- Draft the summary.
- Review for completeness before finalizing.
E — Evaluation
What we found (EXP-003): Across a 6-turn conversation, structural instructions — bullet points, bold headings, a required closing tag — held consistently on every follow-up prompt. A numeric word-limit was the one instruction that slipped: exceeded on the first follow-up, then met on the next two. This is a single-model, single-conversation observation, not a general compliance rate — but it’s a pattern worth planning around. [Read the full EXP-003 writeup →]

Why it matters for teams: Before accepting an output, check it against the instructions that are actually fragile — exact counts and hard numeric limits — not just the ones that are easy to eyeball. A simple review step here catches the failure mode our test actually produced, rather than a generic proofread.
The Path to Standardization: Building a Prompt Library
A standardized prompt library helps teams move from individual prompting habits to repeatable organizational practices. Instead of creating prompts from scratch, employees start from approved templates that reflect the organization’s communication standards and operational requirements.
Prompt libraries improve consistency by separating stable instructions from task-specific information. Teams maintain one approved template while updating only the variables needed for each task.
Step 1: Centralize Approved Prompts
Store validated prompts in a shared location such as Notion, SharePoint, GitHub, or a prompt management platform. A single source of truth reduces duplicate work and makes updates easier to manage. This matters more than it might sound: the entire premise of EXP-001 was that the same task produces radically different output quality depending on how much role and context framing the prompt carries. If every employee is writing that framing from memory each time, you’re re-running the EXP-001 gap — vague vs. structured — on every single task, every single day, purely by chance of who remembers to add context and who doesn’t.
Step 2: Use Variables Instead of Rewriting
Convert static prompts into reusable templates. Lock in role, structure, and format as fixed text — our EXP-003 test found these hold up reliably. Treat exact counts as a range instead of a hard number (see PIPE-009 below) — the same principle applies at the template level, not just the individual prompt.
Step 3: Maintain Version Control
Treat prompt templates as operational documents, not personal notes. Review and update them whenever policies or models change — and include the escape-hatch logic (what to do when data is missing, see PIPE-006 below) in that review, not just tone and branding.
Human-in-the-Loop (HITL): Governance Before Approval
Even well-designed prompts cannot eliminate every error. Human review remains an essential governance layer for business-critical AI outputs, especially when responses influence customers, legal documents, financial decisions, or public communication.
The purpose of HITL is not to rewrite every response. Instead, reviewers verify that the output follows organizational standards before it is approved for use.
A practical review checklist includes:
- Required instructions were followed.
- Facts are supported where necessary.
- Sensitive or confidential information is handled correctly.
- Tone and formatting match organizational standards.
- The response is ready for its intended audience.
Organizations can apply different review levels depending on the risk of the task. Low-risk internal drafts may require only a quick review, while customer-facing or regulated content should receive a more detailed verification before publication.
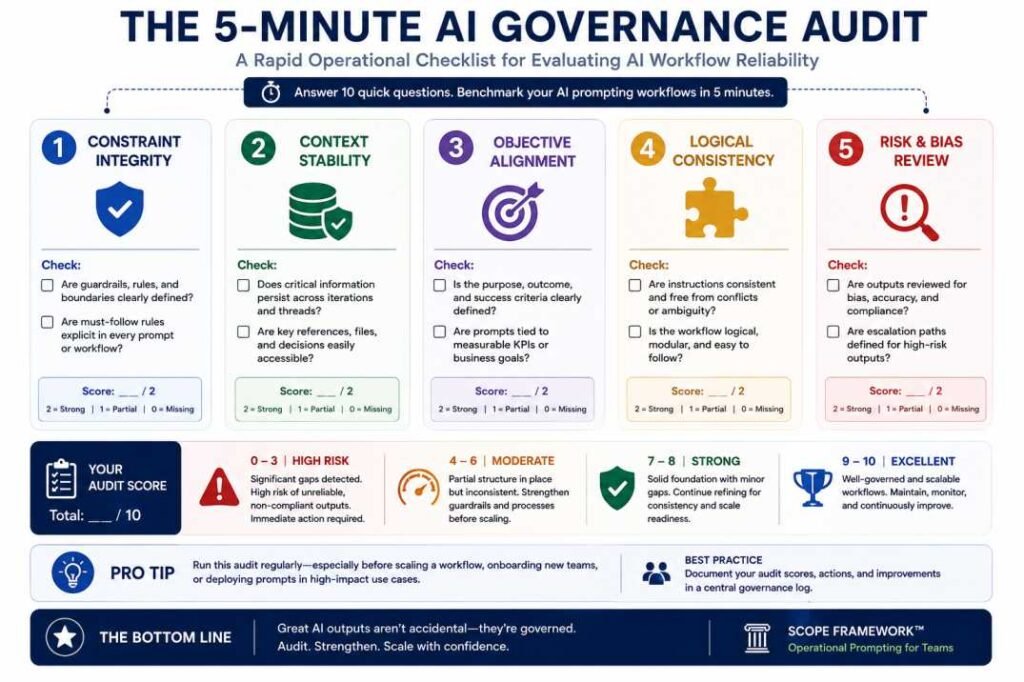
This scoring rubric is a quick internal gut-check, not a statistically validated instrument — treat the 0–10 scale as a rough prioritization tool for where to look first, not a precise risk measurement.
Operational Example: Standardizing Team Prompts
A documented failure pattern, applied to a team scenario: Consider a marketing team producing weekly AI-assisted newsletters, where the shared template requires a “Top 3 Customer Wins” section formatted as a bulleted list that must not be empty. In PIPE-006 (Conflicting Constraints Trap), a model handling an analogous no-empty-output constraint chose factual accuracy over the structural rule — it returned an empty result rather than inventing data, breaking the format. The fix that worked was adding an explicit escape hatch (“if no wins are available, output ‘No wins to report this week'”). Teams building shared templates should watch for a similar failure mode: when a prompt combines strict structural rules with ambiguous input, models often prioritize factual accuracy by returning empty or broken outputs rather than inventing data (as observed in PIPE-006).
Additionally, treat exact-count constraints with caution. As noted in PIPE-009, exact numeric limits (like ‘exactly 175 words’) can be fragile because models generate text sequentially without a live counter. Rewriting these as ranges (e.g., ‘150–200 words’) yields much more stable results.
Strategic Implementation: Getting Started
Organizations do not need to redesign every AI task at once. A practical approach is to standardize one high-impact workflow before expanding to additional use cases.
A simple rollout plan is:
Phase 1 — Identify Repetitive Tasks
Choose one recurring, text-heavy task. A good candidate is one where the current prompt is generic (the EXP-001 pattern: no audience or context framing).
Phase 2 — Build a Shared Prompt Standard
Build the template using the Starter Operational Template above. Add compatible instructions one at a time and check which ones the model consistently keeps — formatting/structural instructions tend to hold better than numeric constraints (EXP-003). Where a hard “must-have” or “must-not-be-empty” rule is used, add an explicit fallback value for missing-data cases (PIPE-006).
Phase 3 — Review and Improve
Run the HITL checklist above on the first 5–10 outputs before wider rollout. If a template specifies an exact count (word limit, number of bullet points), treat it as fragile — PIPE-009 documented that exact-count constraints are unreliable by design (models generate token-by-token without a look-ahead counter) and are better rewritten as a range (“150–200 words” instead of “exactly 175 words”).
Run this three-phase rollout on one workflow first. Once the template survives its first 10 real outputs without a rewrite, expand it to the next team or task.
Final Thoughts: Prompt Engineering Is an Operational Standard
Across the tests referenced here, two patterns hold consistently. First, structural instructions (formatting, tone, closing rules) held up more reliably than precise numeric constraints in our testing — EXP-003 saw a word-limit instruction slip on the first follow-up before recovering, and PIPE-009 found similar fragility with exact-count constraints. Neither test establishes a general failure rate, but the pattern was consistent enough across both that we’d treat any ‘exactly N’ instruction in a shared template as worth rewriting as a range rather than trusting as-is.
Second, when a template combines a strict structural rule with an ambiguous or missing input, models tend to prioritize factual accuracy over the rule — producing an empty or broken output rather than inventing data (PIPE-006). Templates should specify what to do when the expected data isn’t there.
None of this guarantees factual accuracy. The tests referenced here evaluate instruction-following and output structure, not whether the underlying content is correct — human review remains necessary for anything customer-facing or business-critical.
Frequently Asked Questions (FAQ)
How many people need to be on a team before a prompt library is worth building?
A: If more than two people are running the same recurring AI task, the coordination cost of everyone prompting from memory usually exceeds the cost of building one shared template.
Does the SCOPE framework work with any AI model, or only specific ones?
A: The structure itself (role, constraints, format, process, evaluation) is model-agnostic. What isn’t guaranteed to transfer is how reliably a given model holds onto each instruction type — our EXP-003 and PIPE-009 results were observed on a single model in single conversations, so teams switching models should re-test constraint reliability rather than assume it carries over.
Who should own the prompt library once it’s built — IT, a specific department, or someone else?
A: There’s no universal answer, but ownership works best assigned to whichever team is accountable for the output’s quality (e.g., marketing owns the newsletter template, not IT), with a lightweight central index so templates don’t fragment across tools
Resources & Further Reading
To dive deeper into our empirical findings on AI behavior, prompt reliability, and team governance workflows, explore our documented research series:
- EXP-001: Prompt Specificity Test
A controlled observation testing how audience context and role-anchoring alter response utility across multiple iterations. - EXP-002: Instruction Retention Test
An analysis of how LLMs maintain or drop initial constraints across multi-turn, multi-topic enterprise conversations. - EXP-003: Multi-Instruction Compliance Test
Evaluating structural vs. numeric constraint adherence under progressive conversation loads. - PIPE-006: The Conflicting Constraints Trap
A deep dive into why models choose empty outputs over fabricated data when structural rules clash with missing inputs, and how to build fallback loops. - AI Workflows for Teams: Why One-Off Prompts Fail
A structural guide on moving from individual prompt engineering to scalable, human-in-the-loop (HITL) operational pipelines.
- The 4 Prompting Moves That Fix Generic AI Output - September 12, 2026
- How to Evaluate AI Answer Reliability: A 7-Step Verification Framework - August 9, 2026
- AI Memory vs. Context Window: Why Most People Confuse Them (And Why It Matters) - July 23, 2026